arXiv preprint · 2026
Label-Budgeted Attribute Inference from Protected Features in Edge-Cloud Split Multimodal LLMs
Overview
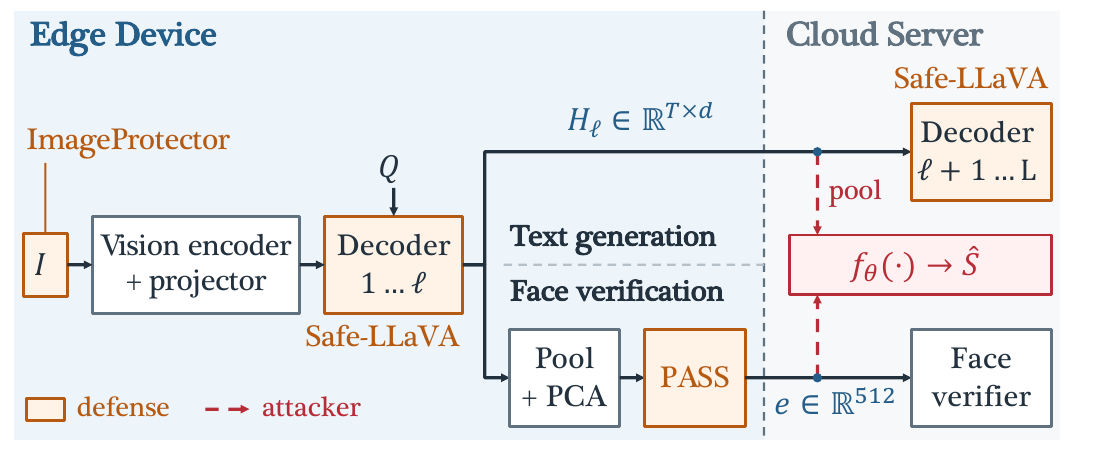
This paper studies what an honest-but-curious server can infer about a user from the intermediate features that an edge device sends in split multimodal LLM inference. Keeping raw images local does not by itself keep attributes such as age, gender, and race private.
Method
The paper proposes a label-budgeted attribute-inference framework. A recovery curve measures what share of the unprotected leakage an attacker recovers as its labeled-sample budget grows, from zero labels to a full labeled set. It is used to evaluate input-level, representation-level, and response-level protections on the transmitted features.
Evaluation
On two popular MLLMs, unprotected features leak all three attributes at every split depth. Protections deployed at other stages still leave information recoverable with small label budgets: Safe-LLaVA removes biometric content from model responses, yet 20 labeled samples per class recover 75–85% of the unprotected leakage from its transmitted features. The results motivate defenses that act on the transmitted representation.
- split inference
- multimodal LLMs
- attribute inference
- privacy
Citation
@article{yao2026label,
  title={Label-Budgeted Attribute Inference from Protected Features in Edge-Cloud Split Multimodal LLMs},
  author={Junguang Yao and Peichun Hua and Hanxiu Zhang and Yue Zheng},
  journal={CoRR},
  volume={abs/2610.32079},
  year={2026},
  url={https://arxiv.org/abs/2610.32079},
  doi={10.48550/arXiv.2610.32079},
  eprinttype={arXiv},
  eprint={2610.32079},
  primaryClass={cs.CR}
}