Accepted · HotNets 2026
Semantics Delivery Network: Rethinking Web Retrieval Infrastructure for LLM Agents
Summary
The Semantics Delivery Network (SemDN) is a proposed delivery layer between websites and LLM agents. Agents reach the web through search services that return URLs and through content delivery networks (CDNs, caches that keep copies of web objects near users) that store whole pages, yet an agent consumes only a few short passages. SemDN indexes, searches, and caches web content as chunks of about 100 to 256 tokens, and preliminary measurements show that page-first retrieval processes 107 times more content than agents consume.
Key numbers
- 107×Median content processed by lightweight HTML retrieval (761 KB) compared with the chunks an agent consumes (7.1 KB) per live-web query
- 73.8%Share of chunk requests served by a 1.34 MB chunk cache in a Search-R1 trace replay
- 3.5–8.2 pointsAccuracy advantage of chunks over whole pages on CRAG at reader budgets from 256 to 6,144 tokens
Method
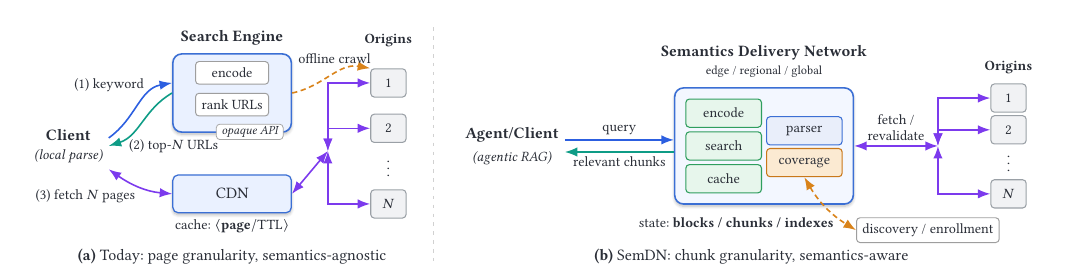
Retrieval-augmented generation (RAG) [1] and multi-turn agentic search both ground a model in retrieved text, and agents such as Search-R1 [2] issue several queries per task. The web path they use was built for human readers. A search engine results page (SERP) returns URLs and snippets, and a CDN caches objects addressed by URL, so neither knows which passage an agent needs. Each agent also fetches, cleans, chunks, and embeds (turns into a vector) the same content on its own.
In SemDN, origins (the websites that own the content) enroll with the network, much as they do with a CDN. A client sends a query instead of a URL to its nearest edge, a point of presence (PoP) that encodes the query, searches an index, and returns ranked chunks. Edge PoPs hold hot content and index state, regional parents hold larger and colder shards, and a global tier keeps the catalog. Normalized content blocks and a canonical index are shared across clients, while each client keeps its own reranker and utility function private.
Semantic search always returns top-k results, so a cache miss cannot be observed as it can for a URL. A coverage controller estimates the risk that fresh evidence exists outside the index, using retrieval-score distributions, whether the evidence suffices to answer, agreement across tiers, and freshness metadata. When the risk passes a threshold, it calls an external discovery service and refreshes the affected content.
Evaluation
The measurements are preliminary. For 100 live-web queries, a median of 7.1 KB of selected chunks is consumed, while a lightweight HTML fetch processes 761 KB to obtain them (107×) and a full browser render yields 18.1 MB. At least 39% of 500 sampled URLs lose more than half of their text without JavaScript, and about 19% block bots, which makes per-client fetching heavy and failure-prone.
Agentic queries repeat. In Search-R1 runs over wiki-18, a 21-million-chunk Wikipedia corpus built for open-domain QA [3], 30.5% of the queries after the first turn are byte-identical repeats within a task, and 32 to 55% of a new query's chunks were already retrieved earlier in the task. A chunk-granularity LRU cache (least-recently-used eviction) of 1.34 MB serves 73.8% of chunk requests and sends 13 to 41 times fewer bytes to origin than a URL-object cache of equal size. On the CRAG benchmark [4], the advantage in origin bytes rises to 25 to 70 times.
Chunks also answer better per token. With the same reranker, chunks beat whole pages by 3.5 to 8.2 accuracy points at reader budgets from 256 to 6,144 tokens. On five QA sets over wiki-18, chunks match or beat a page-first client that downloads ten pages (accuracy 0.456 against 0.427 with the e5 ranker) while moving about 1,200 times fewer bytes. A model of Zipfian demand estimates about 6 times less repeated fetch-clean-chunk-embed work at 50 tenants.
| Measure | Page or URL path | SemDN chunk path |
|---|---|---|
| Median content per live-web query | 761 KB lightweight HTML | 7.1 KB consumed chunks |
| Bytes to origin at equal cache capacity | 13–41× more (URL-object LRU) | 1× (chunk LRU) |
| CRAG-metric accuracy, five QA sets, e5 ranker | 0.427 (top 10 pages, 3.8 MB HTML) | 0.456 (chunks, 3.2 KB) |
Limitations
This is a position paper with preliminary evidence. The cache results are trace-driven simulations, and the cross-tenant saving comes from a demand model: the top-10 domains draw 34% of results in the live set, which suggests overlap and does not show that tenants request the same pages. The advantage of chunks narrows above 8K tokens of reader context, where the context already holds most of the supporting evidence.
Open problems remain in deployment. Calibrating coverage risk under content drift is unsolved. Origins and clients each need a reason to pay. A shared cache can leak one tenant's queries through timing, and an operator paid by origins could rank paying origins higher. Verifiable search over a committed index takes 0.8 to 2 seconds per query today.
- agentic search
- retrieval-augmented generation
- content delivery networks
- semantic caching
- web retrieval
- edge computing
Citation
@inproceedings{hua2026semantics,
  title={Semantics Delivery Network: Rethinking Web Retrieval Infrastructure for LLM Agents},
  author={Peichun Hua and Yunming Xiao},
  booktitle={The 25th ACM Workshop on Hot Topics in Networks (HotNets '26)},
  year={2026},
  publisher={Association for Computing Machinery},
  address={New York, NY, USA},
  url={https://doi.org/10.1145/3847290.3859940},
  doi={10.1145/3847290.3859940},
  numpages={13},
  keywords={Content Delivery Networks, Retrieval-Augmented Generation, Agentic Search, Semantic Caching, Vector Search},
  location={Salt Lake City, UT, USA},
  series={HotNets '26}
}
References
- Patrick Lewis et al. Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks. NeurIPS, 2020. arxiv.org/abs/2005.11401
- Bowen Jin et al. Search-R1: Training LLMs to Reason and Leverage Search Engines with Reinforcement Learning. arXiv, 2025. arxiv.org/abs/2503.09516
- Vladimir Karpukhin et al. Dense Passage Retrieval for Open-Domain Question Answering. EMNLP, 2020. arxiv.org/abs/2004.04906
- Xiao Yang et al. CRAG: Comprehensive RAG Benchmark. NeurIPS Datasets and Benchmarks, 2024. arxiv.org/abs/2406.04744